위치:
홈 >
τ Scaling · Huawei's Tau Law: LogicFolding Ushers the Post-Moore Era

τ Scaling · Huawei's Tau Law: LogicFolding Ushers the Post-Moore Era

Unified time-scaling from transistor to datacenter, delivering 100x integration by 2035

2026-05-25 15:56
QR 코드
29
τ Scaling · Huawei's Tau Law | LogicFolding Ushers Post-Moore Era
📄 Paper source: Tingbo He (Huawei Semiconductor) — "A Time Scaling Theory for Multi-Layer Electronic Systems"🔗 ChinaXiv:202605.00224 · Read full text⚡ τ scaling | Post-Moore unified optimization metric

τ Scaling · Huawei's Tau Law: LogicFolding Ushers the Post-Moore Era

Unified time-scaling from transistor to datacenter, delivering 100x integration by 2035

Keywords: τ scaling, LogicFolding, Huawei, Kirin, post-Moore, 3D folding, Unified Bus, Hi-ONE, optical I/O, time constant, semiconductor, Ascend, hybrid bonding, EDA
Description: Huawei's τ scaling theory unifies 12 orders of magnitude. LogicFolding delivers +55% density, +41% efficiency at fixed node. Unified Bus cuts latency 500x, Hi-ONE optical I/O 8Tb/s, 3D folding >100x integration by 2035. Post-Moore roadmap for AI and mobile SoCs.
Abstract: Six decades of Moore's geometric scaling have ended. This paper proposes τ scaling — using characteristic time constant τ as the unified optimization target across 12 orders of magnitude. LogicFolding on mobile SoCs achieves +55% density and +41% energy efficiency at a fixed node. Co‑designed protocol stack predicts >100× hardware integration growth by 2035.
🧠 τ scaling · global mindmapunified time constant
root(("τ scaling · Time scaling theory"))
  (Core definition)
    τ = f(τ_transistor, τ_circuit, τ_chip, τ_system)
    spans 12 orders of magnitude (ps → sec)
    α scaling: τ_{n+1}=τ_n/α
  (LogicFolding · Mobile SoC)
    hybrid bonding pitch ≤1.5μm
    density 155→238 MTr/mm²
    energy efficiency +41% / freq +13%
    clock skew -25%, wirelength -30%
  (AI system τ optimization)
    Unified Bus: 500x latency cut (μs→100ns)
    Hi-ONE optical I/O: 8Tb/s, 100m links
    fan-out dilemma → 3D folding solution
  (3D folding & integration)
    vertical surfaces for memory/optics
    N² scaling for all resources
    >100x hardware integration by 2035
  (Logic + memory refusion)
    HBM / hybrid bonding / 3D SRAM
    industry ecosystem reshaping
  (Open challenges)
    3D-native EDA tools
    wafer-to-wafer variation / vertical RC
    energy companion: τ margin for power
⏱️
τ·Core Axiom

Characteristic time constant τ becomes the unified optimization goal across transistor → system. Geometric scaling is just one tool; vertical integration, optics, and architecture all contribute to τ reduction.

⏳ covers 12 orders of magnitude
📱
LogicFolding · 3D folding

Kirin 2026 first to implement: density +55% (155→238 MTr/mm²), energy efficiency +41%, max frequency +13% to 3.1GHz. SRAM operating frequency +40%.

🔻 leap at fixed node
🚀
Unified Bus · In-memory semantics

Single memory semantic protocol replaces PCIe/NVLink/Ethernet, end-to-end latency ~100ns (500× improvement). Hardware-managed coherence, rack-level "system-as-one-chip".

📡 500x latency cut
💡
Hi-ONE Optical I/O Engine

Near-package optics, 8Tb/s per module, SerDes distance shrunk to 5cm, 100-meter inter-rack links. Breaks copper interconnect bottleneck.

🔆 matches AI bandwidth demands
🧩
3D Folding · Solving fan-out dilemma

2.5D packaging: compute area grows as N² but I/O and power only as N → 3D folding moves resources to vertical surfaces, enabling N² scaling for all. >100× integration by 2035.

⚡ restores area scaling
📊
Performance roadmap

Kirin 2029 CPU frequency targets 4GHz+ ; Ascend 990 (2030) adopts LogicFolding; hardware integration >100× by 2035.

📅 τ-driven post-Moore planning

A Time Scaling Theory for Multi-Layer Electronic Systems

Author: Tingbo He (Huawei Semiconductor) | Leading LogicFolding from theory to mass production

📌 Abstract: Six decades of Moore’s geometric scaling have come to an end. Transistor cost no longer decreases at leading nodes. This paper proposes τ scaling — using the characteristic time constant τ as the unified optimization target across 12 orders of magnitude (transistor → datacenter). LogicFolding on mobile SoCs achieves +55% density and +41% energy efficiency at a fixed node. For AI systems, co‑designed protocol stack (unified memory‑semantic bus, Hi‑ONE optical I/O, and 3D folding) predicts >100× hardware integration growth by 2035. τ scaling becomes the first end‑to‑end scaling principle since Dennard scaling.

ISCAS 2026 live announcement: Huawei Board Director & President of Semiconductor Business, Tingbo He, officially introduces the "Tau (τ) Law".

The Kirin mobile chip launching this fall will be the first to adopt LogicFolding technology, delivering substantial performance gains.

He’s paper "A Time Scaling Theory for Multi-Layer Electronic Systems" was submitted today to the ChinaXiv preprint platform, detailing the τ Law and outlining Huawei’s future chip development roadmap.
τ scaling principle diagram

He argues that the pure "geometric era" of the chip industry has ended.

Moore’s Law only addresses the time dimension (transistor count doubling every 18–24 months), and the era of per-layer independent optimization is also over.

The first production‑scale test of the τ Law is carried out on mobile devices.

A smartphone SoC is a rare case where a single chip constitutes the whole system: multi‑socket parallelism is unavailable, no thousand‑node architecture can hide slow connections, and total power is only a few watts under thermal constraints.

After 2020, when access to advanced nodes became restricted, the practical problem became: with a fixed process node, how to deliver generation‑over‑generation performance improvements on a single chip?

The answer that emerged is LogicFolding.

LogicFolding is a design methodology that partitions digital, analog, and memory circuits into vertically stacked active layers, jointly optimizing performance, power, and area according to time‑scaling principles.

Kirin 2026 silicon results:

  • Transistor density stepped from 155 MTr/mm² to 238 MTr/mm² in a single generation — an improvement that previously required three years of geometric scaling.
  • SoC performance core energy efficiency improved by 41%, and maximum clock frequency rose by nearly 13% to 3.1GHz.
  • High‑speed global Network‑on-Chip (NoC) data paths reduced area by 55% and improved power delivery stability.
  • Post‑silicon clock skew adjustment contributed >5% additional SoC performance.
  • For SRAM — where access speed, energy/bit, and area heavily depend on bit‑line and word‑line length — LogicFolding shortens critical paths, reduces energy/bit, and raises operating frequency by over 40%.
  • On a typical processing core, dual‑layer folding reduces clock buffer count by >50%, lowers clock skew by 25%, and cuts routing length by about 30%.

These gains are achieved on a fixed device node, not through new lithography steps, but through topological reorganisation of logic in three dimensions.

The LogicFolding implemented in Kirin 2026 is deliberately conservative: hybrid bonding pitch is 1.5μm, and folding is applied selectively only to critical paths, not across the entire design.
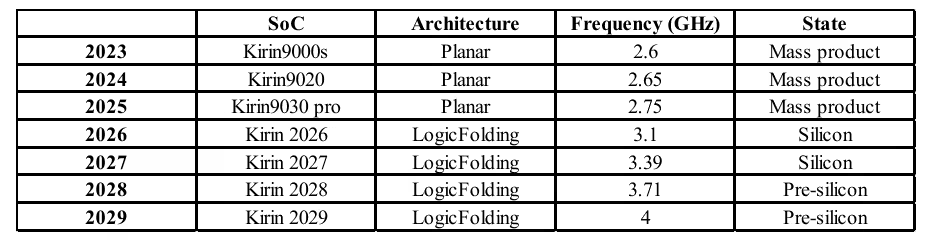
Kirin roadmap and projections

Over the next decade, LogicFolding will evolve from local critical‑path folding to full‑scale multi‑layer folding — three, four, or more active layers per package.

From 2026 to 2035, transistor density is expected to reach 400 MTr/mm² or higher.

At the same time, LogicFolding paves the way for CPU core frequencies to reach 4 GHz and beyond.

The roadmap is both technically feasible and economically viable.

Kirin chip naming: the paper shows Kirin 2026, 2027, 2028, 2029.

Kirin 2027 is already marked as "Silicon" (substantial progress), while Kirin 2028/2029 are in pre‑silicon phase.

For AI accelerators: Ascend 910C, 950, and by 2030 Ascend 990 will also introduce LogicFolding, with hardware integration expected to exceed 100× by 2035.

The Unified Bus adopts a single memory‑semantic protocol, cutting end‑to‑end remote access latency to ~100ns (a 500× improvement).

The Hi‑ONE optical engine delivers 8Tb/s per module, dramatically reducing power and complexity.

3D folding resolves the fan‑out dilemma by moving storage and optical I/O from the periphery to vertical surfaces, enabling N² scaling for all resources and restoring area‑derived benefits.

💡 Industry significance: τ scaling provides a new post‑Moore metric. Instead of relying on expensive EUV iterations, it sustains performance growth through 3D integration and system‑level time‑constant optimisation. Huawei has demonstrated a full stack from LogicFolding to unified bus and co‑packaged optics.

Kirin roadmap (data from paper)

ChipStatusLogicFolding generationExpected density/frequency
Kirin 2026Mass productionConservative (local critical paths)238 MTr/mm², 3.1GHz, +41% efficiency
Kirin 2027Silicon (taped out)Enhanced foldingHigher density/frequency
Kirin 2028Pre‑siliconMulti‑layer folding (3 layers)towards 3.6GHz+
Kirin 2029Pre‑siliconFull‑scale foldingtarget 4GHz+

Ascend AI accelerators will adopt LogicFolding around 2030; Ascend 990 will drive >100× hardware integration gain (compared to 2026 baseline).

The paper also highlights open challenges: need for 3D‑native EDA tools, wafer‑to‑wafer process variation compensation, vertical interconnect RC tradeoffs, and energy‑companion design.

τ scaling provides a fresh benchmarking framework to guide post‑Moore investment.

Paper link: https://chinaxiv.org/abs/202605.00224 (open access preprint)

Analysis & Strategic Outlook

τ scaling represents a fundamental shift from geometric to temporal optimization. By unifying latency across 12 orders of magnitude, it enables co‑design of device, circuit, and system. LogicFolding demonstrates that 3D topological reorganisation can outperform two generations of Moore's Law at a fixed node. The combination of Unified Bus and Hi‑ONE optics attacks the memory and I/O walls simultaneously, while 3D folding solves the fan‑out dilemma. For the Chinese semiconductor industry, this provides a viable path independent of EUV lithography. The roadmap to 4GHz CPUs and 100× integration by 2035 is credible, provided EDA toolchains and thermal management keep pace. τ scaling also offers a new benchmarking metric that could reshape investment and R&D priorities across the global semiconductor ecosystem.

Core Problem · Solution · Execution & Acceptance

Problem: Moore's geometric scaling has ended; transistor cost no longer decreases at leading nodes. Performance gains via traditional node shrinks are economically and technically unsustainable.

Solution: Adopt τ scaling as the unified optimization metric, using 3D folding (LogicFolding), unified memory‑semantic bus, and co‑packaged optics to reduce characteristic time constant across all layers.

Execution: Kirin 2026 implements conservative LogicFolding with hybrid bonding (1.5μm pitch). Next generations scale to multi‑layer active stacking (3–4 layers) and full‑chip folding, while the Unified Bus and Hi‑ONE optics roll out in AI systems. By 2035, achieve >100× hardware integration.

Acceptance Model: Verify τ reduction at each level: transistor RC, circuit delay, chip clock skew, system latency. Silicon measurements show +55% density, +41% energy efficiency, 500× latency cut. Roadmap milestones: Kirin 2029 4GHz+, Ascend 990 with LogicFolding by 2030.

💬 Technical discussion · selected comments

Q
Qian Zhang, semiconductor veteran2026-05-25
τ scaling unifies device and system latency under one metric — true top‑down thinking. LogicFolding’s 55% density gain at a fixed node is stunning. China’s 3D integration takes a unique path.
L
Li Ying, architect2026-05-25
Unified bus + optical I/O solves the memory wall and protocol overhead, squeezing system τ from microseconds down to 100ns. Server architecture will be reinvented.
W
Wang Wei, EDA researcher2026-05-25
The paper’s emphasis on 3D folding & EDA challenges is spot on. Legacy 2D tools can’t handle continuous 3D entities; an industry‑wide effort is urgently needed.
C
Chen Yuan, AI chip designer2026-05-25
LogicFolding coming to Ascend 990 by 2030 will be a game changer. Starting from mobile SoC and then migrating to AI accelerators is a pragmatic strategy.
L
Liu, near-memory computing enthusiast2026-05-25
SRAM frequency +40% due to 3D folding is phenomenal. Vertical interconnects will give near‑memory and in‑memory computing a second wind.
Z
Zhao Bo, advanced packaging expert2026-05-25
1.5μm hybrid bonding pitch is a practical starting point, far denser than micro‑bumps. The economic viability of multi‑layer active stacks by 2035 is worth watching.
S
Sun, SoC clock specialist2026-05-25
Post‑silicon skew adjustment contributes 5% performance while cutting clock buffers by 50% and routing length 30%. LogicFolding’s physical benefits exceed expectations.
Z
Prof. Zhou, microelectronics2026-05-25
τ law provides a fresh framework for post‑Moore education: shifting from chasing linewidth to optimizing system time constant. Students need cross‑layer design thinking.
W
Wu, former Huawei engineer2026-05-25
When advanced nodes became restricted, we turned to 3D stacking and architecture innovation. Now LogicFolding goes mainstream — a milestone for alternative semiconductor paths.
Z
Zheng, semiconductor investment advisor2026-05-25
Value chain will shift: advanced packaging, hybrid bonding equipment, 3D EDA enter a golden decade. τ scaling quantifies ROI and guides capital allocation.

⌨️ From semiconductor engineer & architect community · hot discussion at ISCAS 2026

© Huawei Semiconductor · τ scaling open collaboration initiative | Data based on ISCAS 2026 paper & Kirin/Ascend public roadmap 2026
첨부 파일 다운로드(1):
이름:
내용:
인증 코드:
의견을 제출하려면
댓글
위치:
홈 >
τ Scaling · Huawei's Tau Law: LogicFolding Ushers the Post-Moore Era
Phone
+8613360508085
Whatsapp
Whatsapp
온라인
온라인
在线客服系统